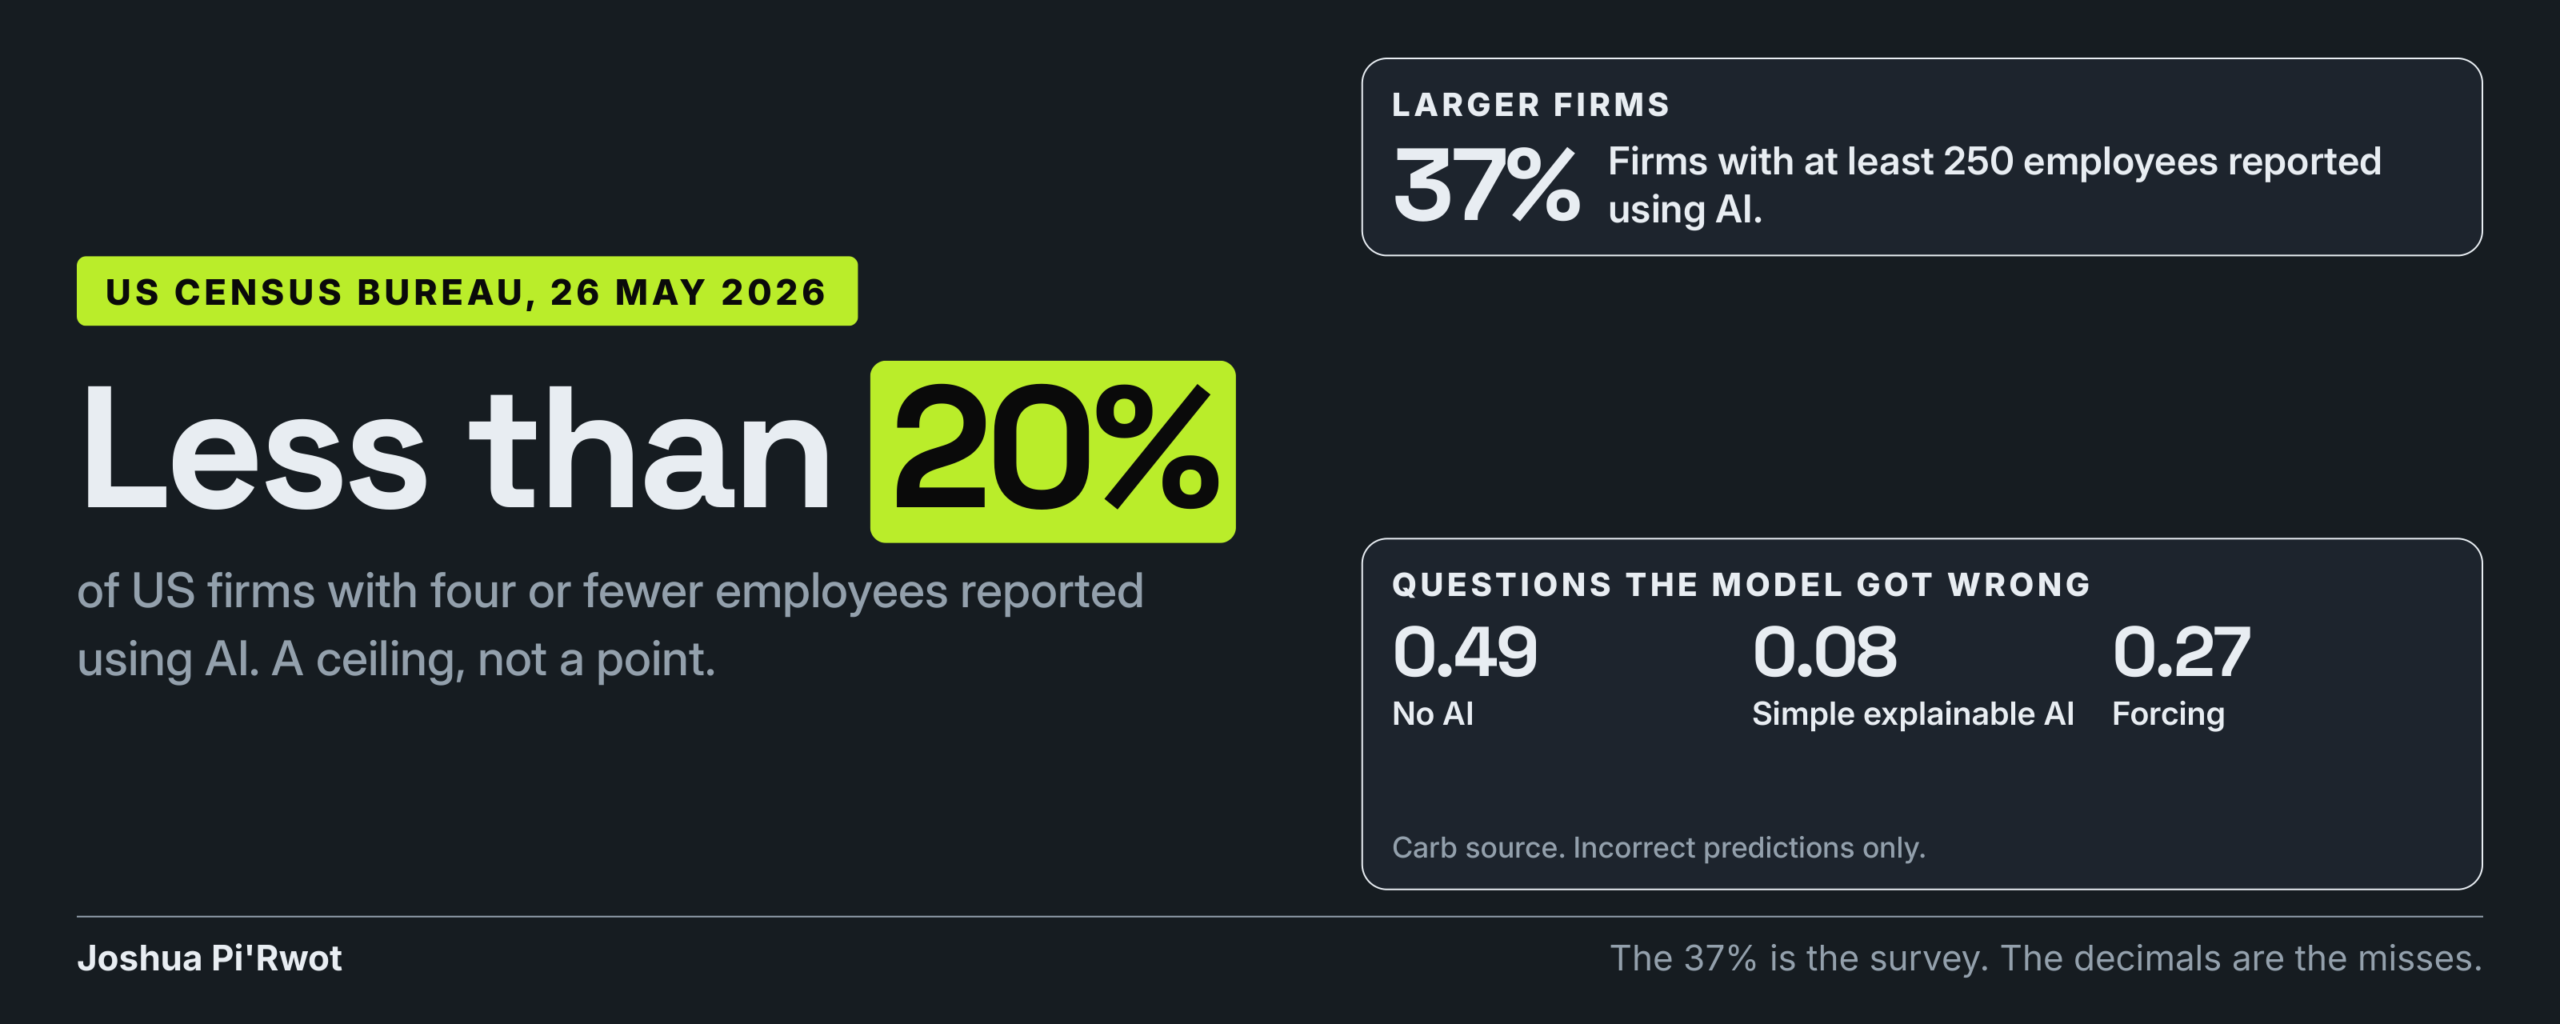
Less than 20% of US firms with four or fewer employees reported using AI. That line is in a Census Bureau story dated 26 May 2026, written by Adam Grundy, Cory Breaux and Dhanapati Khatiwoda. The survey is the Business Trends and Outlook Survey. The authors reviewed collections from 14 December 2025 through 3 May 2026.
The story prints a ceiling, not a point. I am not going to call it 19. The share for that band sits somewhere under the line they published.
What moved, and what held still
From December 2025 to May 2026, use increased among firms with at least 20 employees. It did not change significantly among firms with fewer than 20.
Firms with at least 250 employees: 37% reported using AI. That 37% is not pinned to the single collection ending 3 May. For the period ending 3 May 2026, 32% of firms with 100 to 249 employees reported using AI. The national rate that period was 19.8%. Information was at 39.7%. Finance and Insurance was at 33.9%. Neither sector had shifted significantly since December. Retail trade sat around 14%, and about 17% expected to use AI in the next six months.
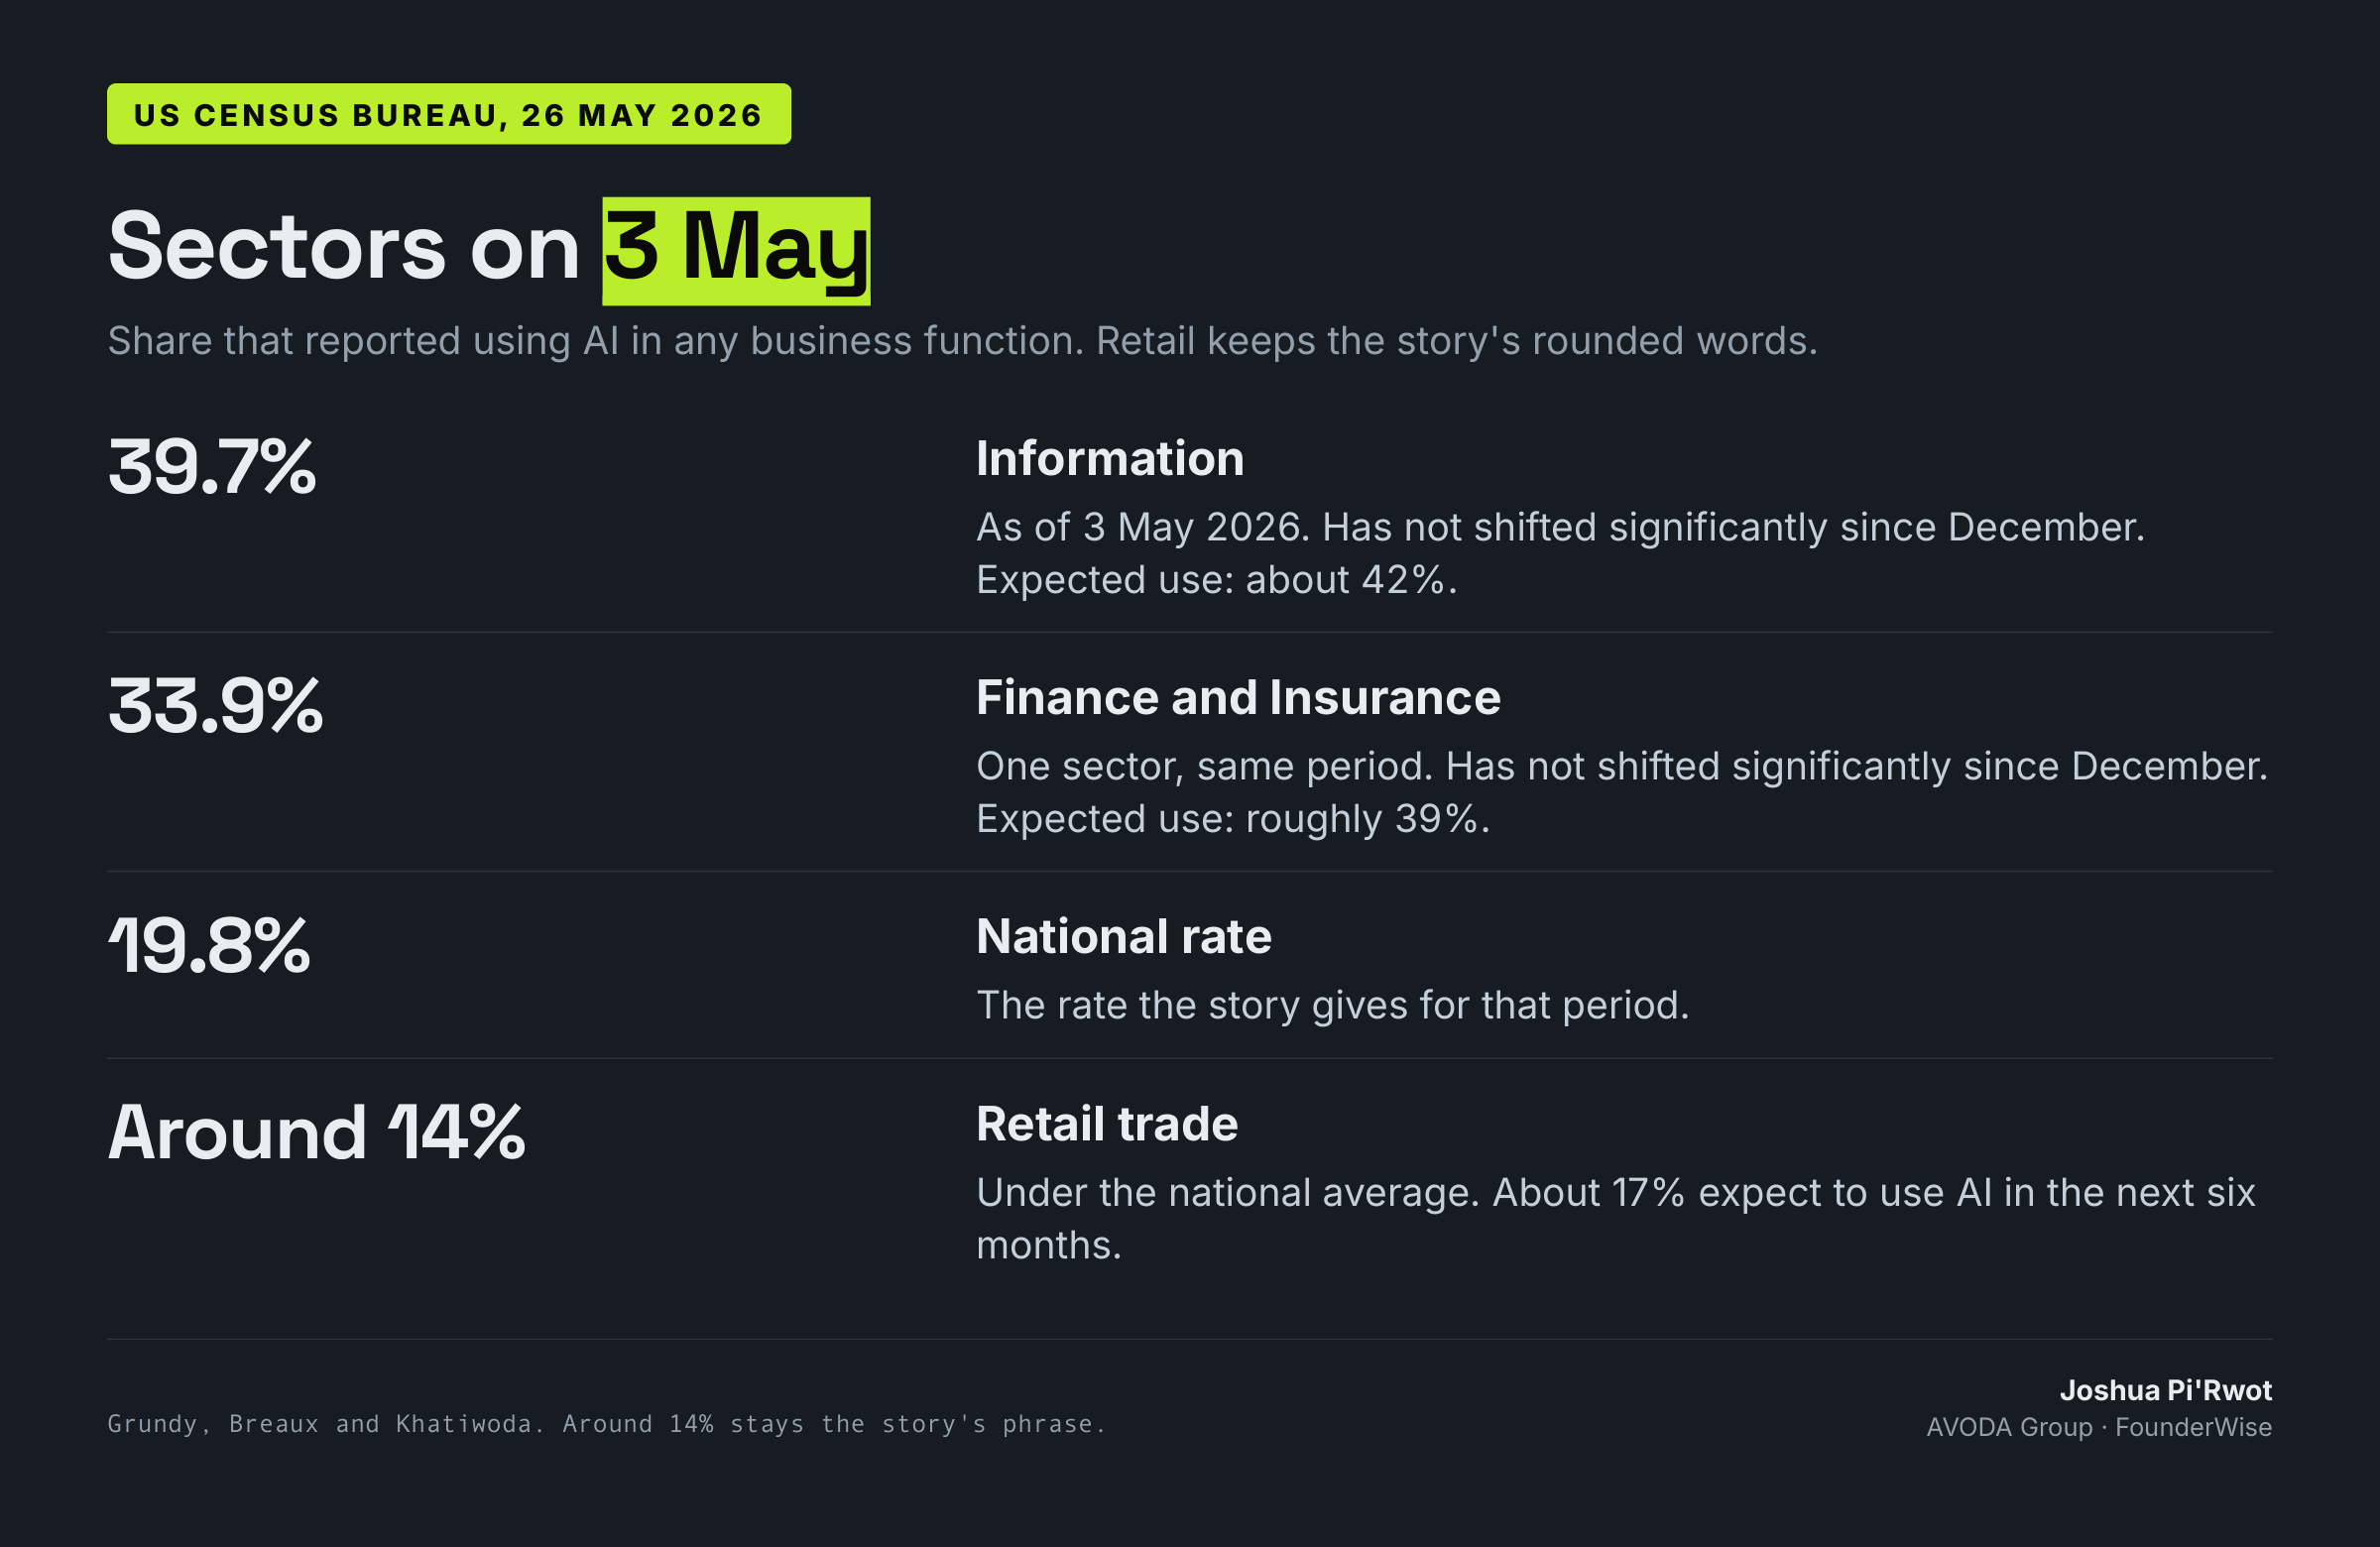
Across all firms, over those six months, use hovered between 17% and 20%. Between 20% and 23% expected to use it in the next six months.
On 17 November 2025 the question changed. Before, it asked about AI use in producing goods or services. After, it asked about use in any business function. The line about four-person firms answers that wider question.
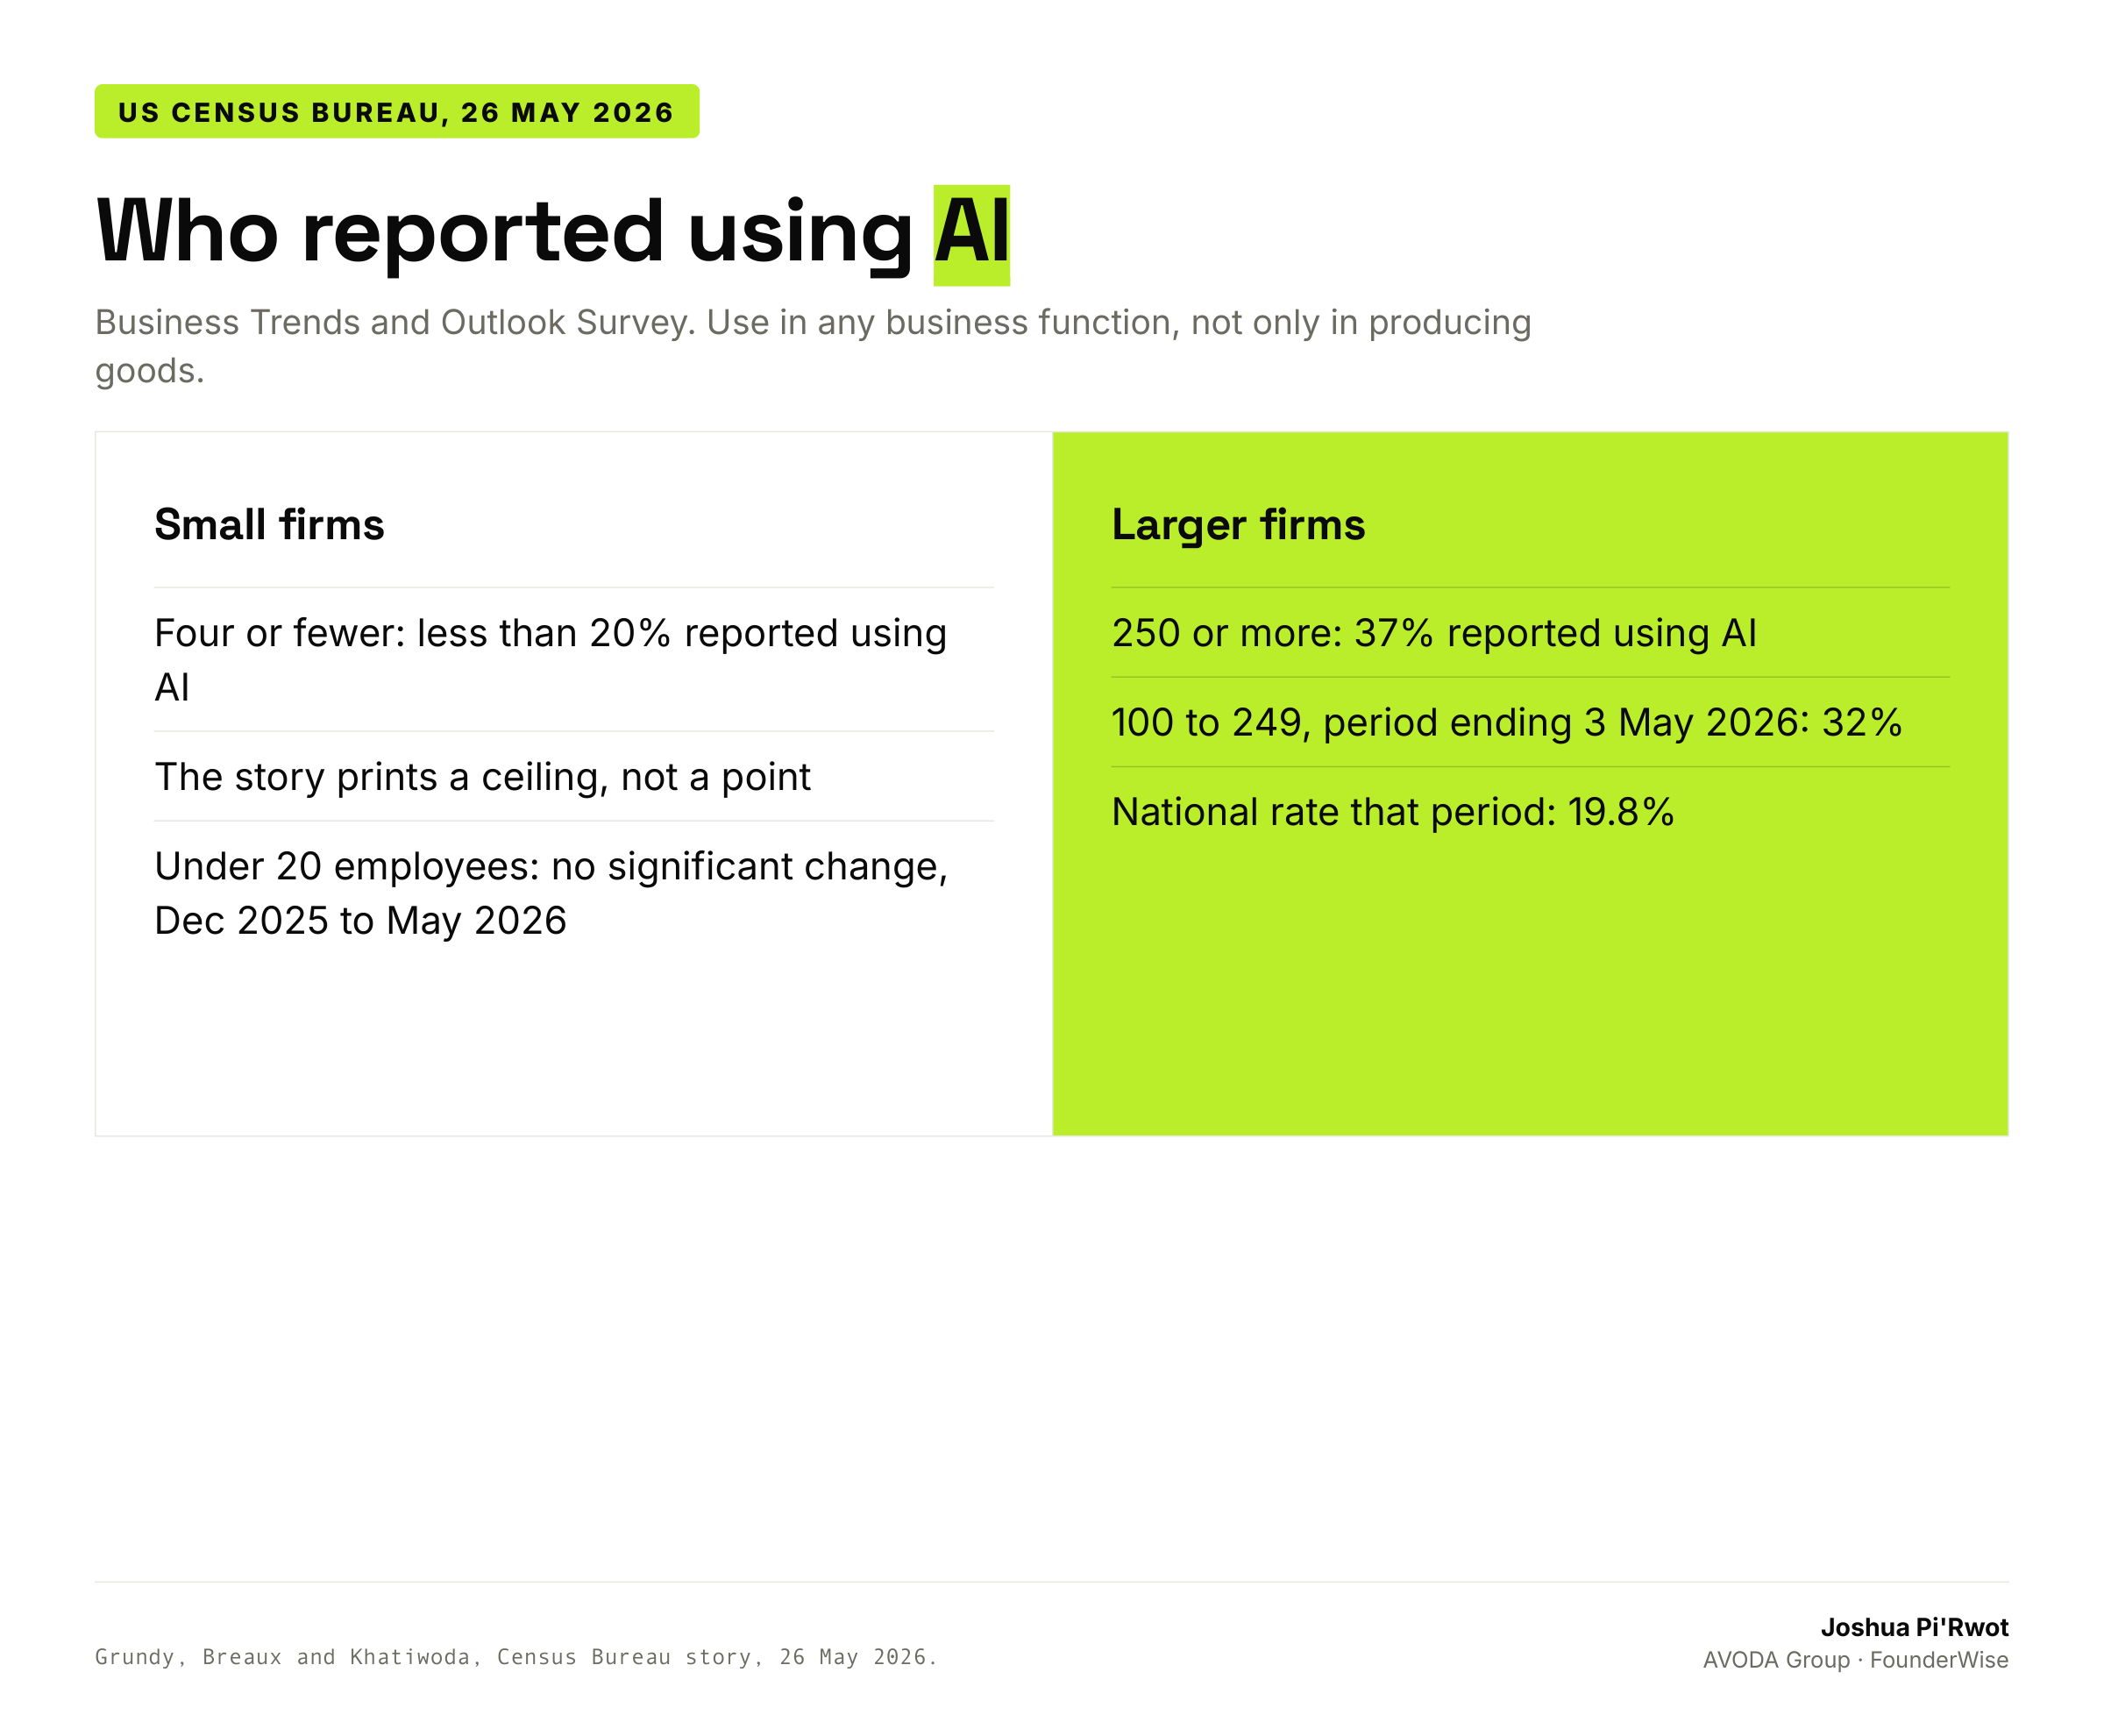
The story cannot see one shop’s books. For firms under 20 employees, it says the rate did not change significantly across those six months.
The questions the model got wrong
Once a firm does use a model, one version of the advice puts the reasoning and the sources on the screen. Another adds a mark for how sure the model is. The two studies report the questions the system got wrong, and the questions it got right. On the questions it got right, the tool helped.
Zana Buçinca, Maja Barbara Malaya and Krzysztof Z. Gajos published the first study in April 2021. People looked at a plate of food, picked the ingredient highest in carbohydrates, and replaced it with something that cut the carbs and stayed close in flavor. The model was a simulation, set at 75% accuracy. When it was wrong, it missed the high-carb ingredient, which the experimenters had made obvious, and pointed at a low-carb one instead. After the filters, 199 people remained.
On all questions together, both assisted groups beat the group with no model. Overall performance was 0.17 with no AI, 0.35 with a simple explanation, and 0.33 when people had to do something before accepting the suggestion.
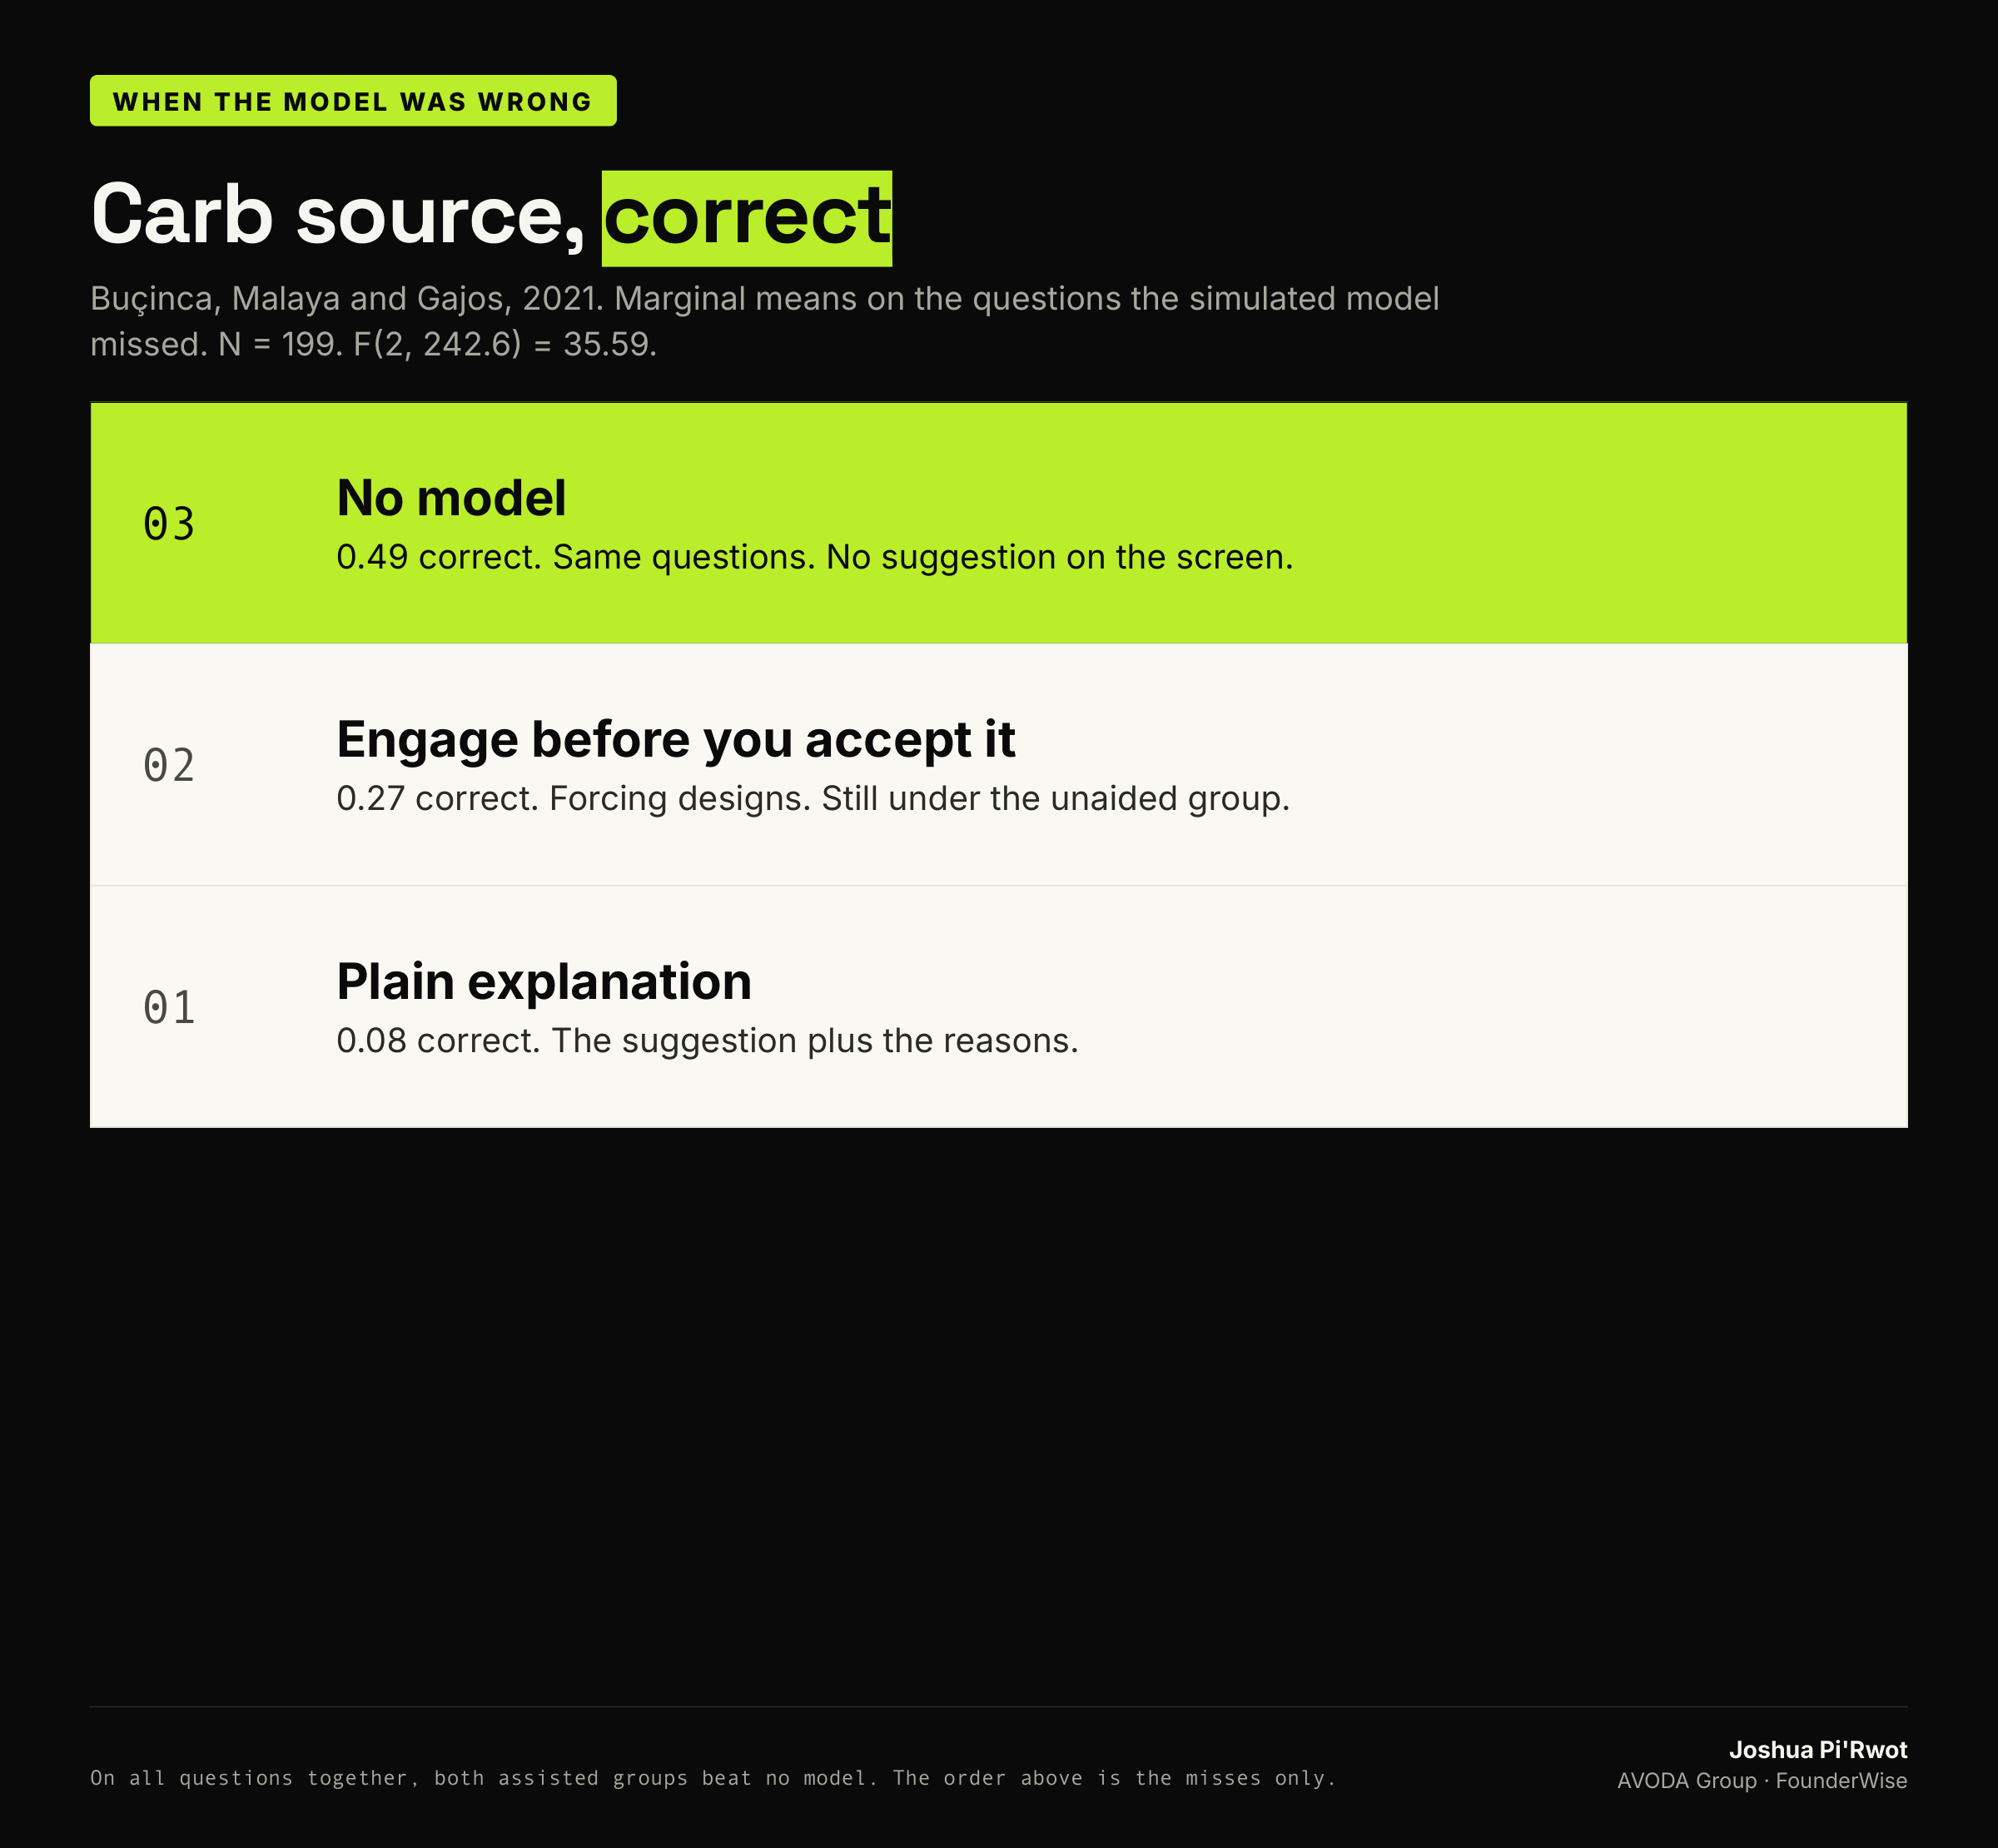
On the incorrect predictions, the order reversed. For which ingredient held the carbs: no AI 0.49, simple explanation 0.08, forcing 0.27. Standard errors 0.04, 0.03 and 0.03. F(2, 242.6) = 35.59. Forcing means the designs that made a person act before simply reading the suggestion. It beat the plain explanation. It did not catch the unaided group.
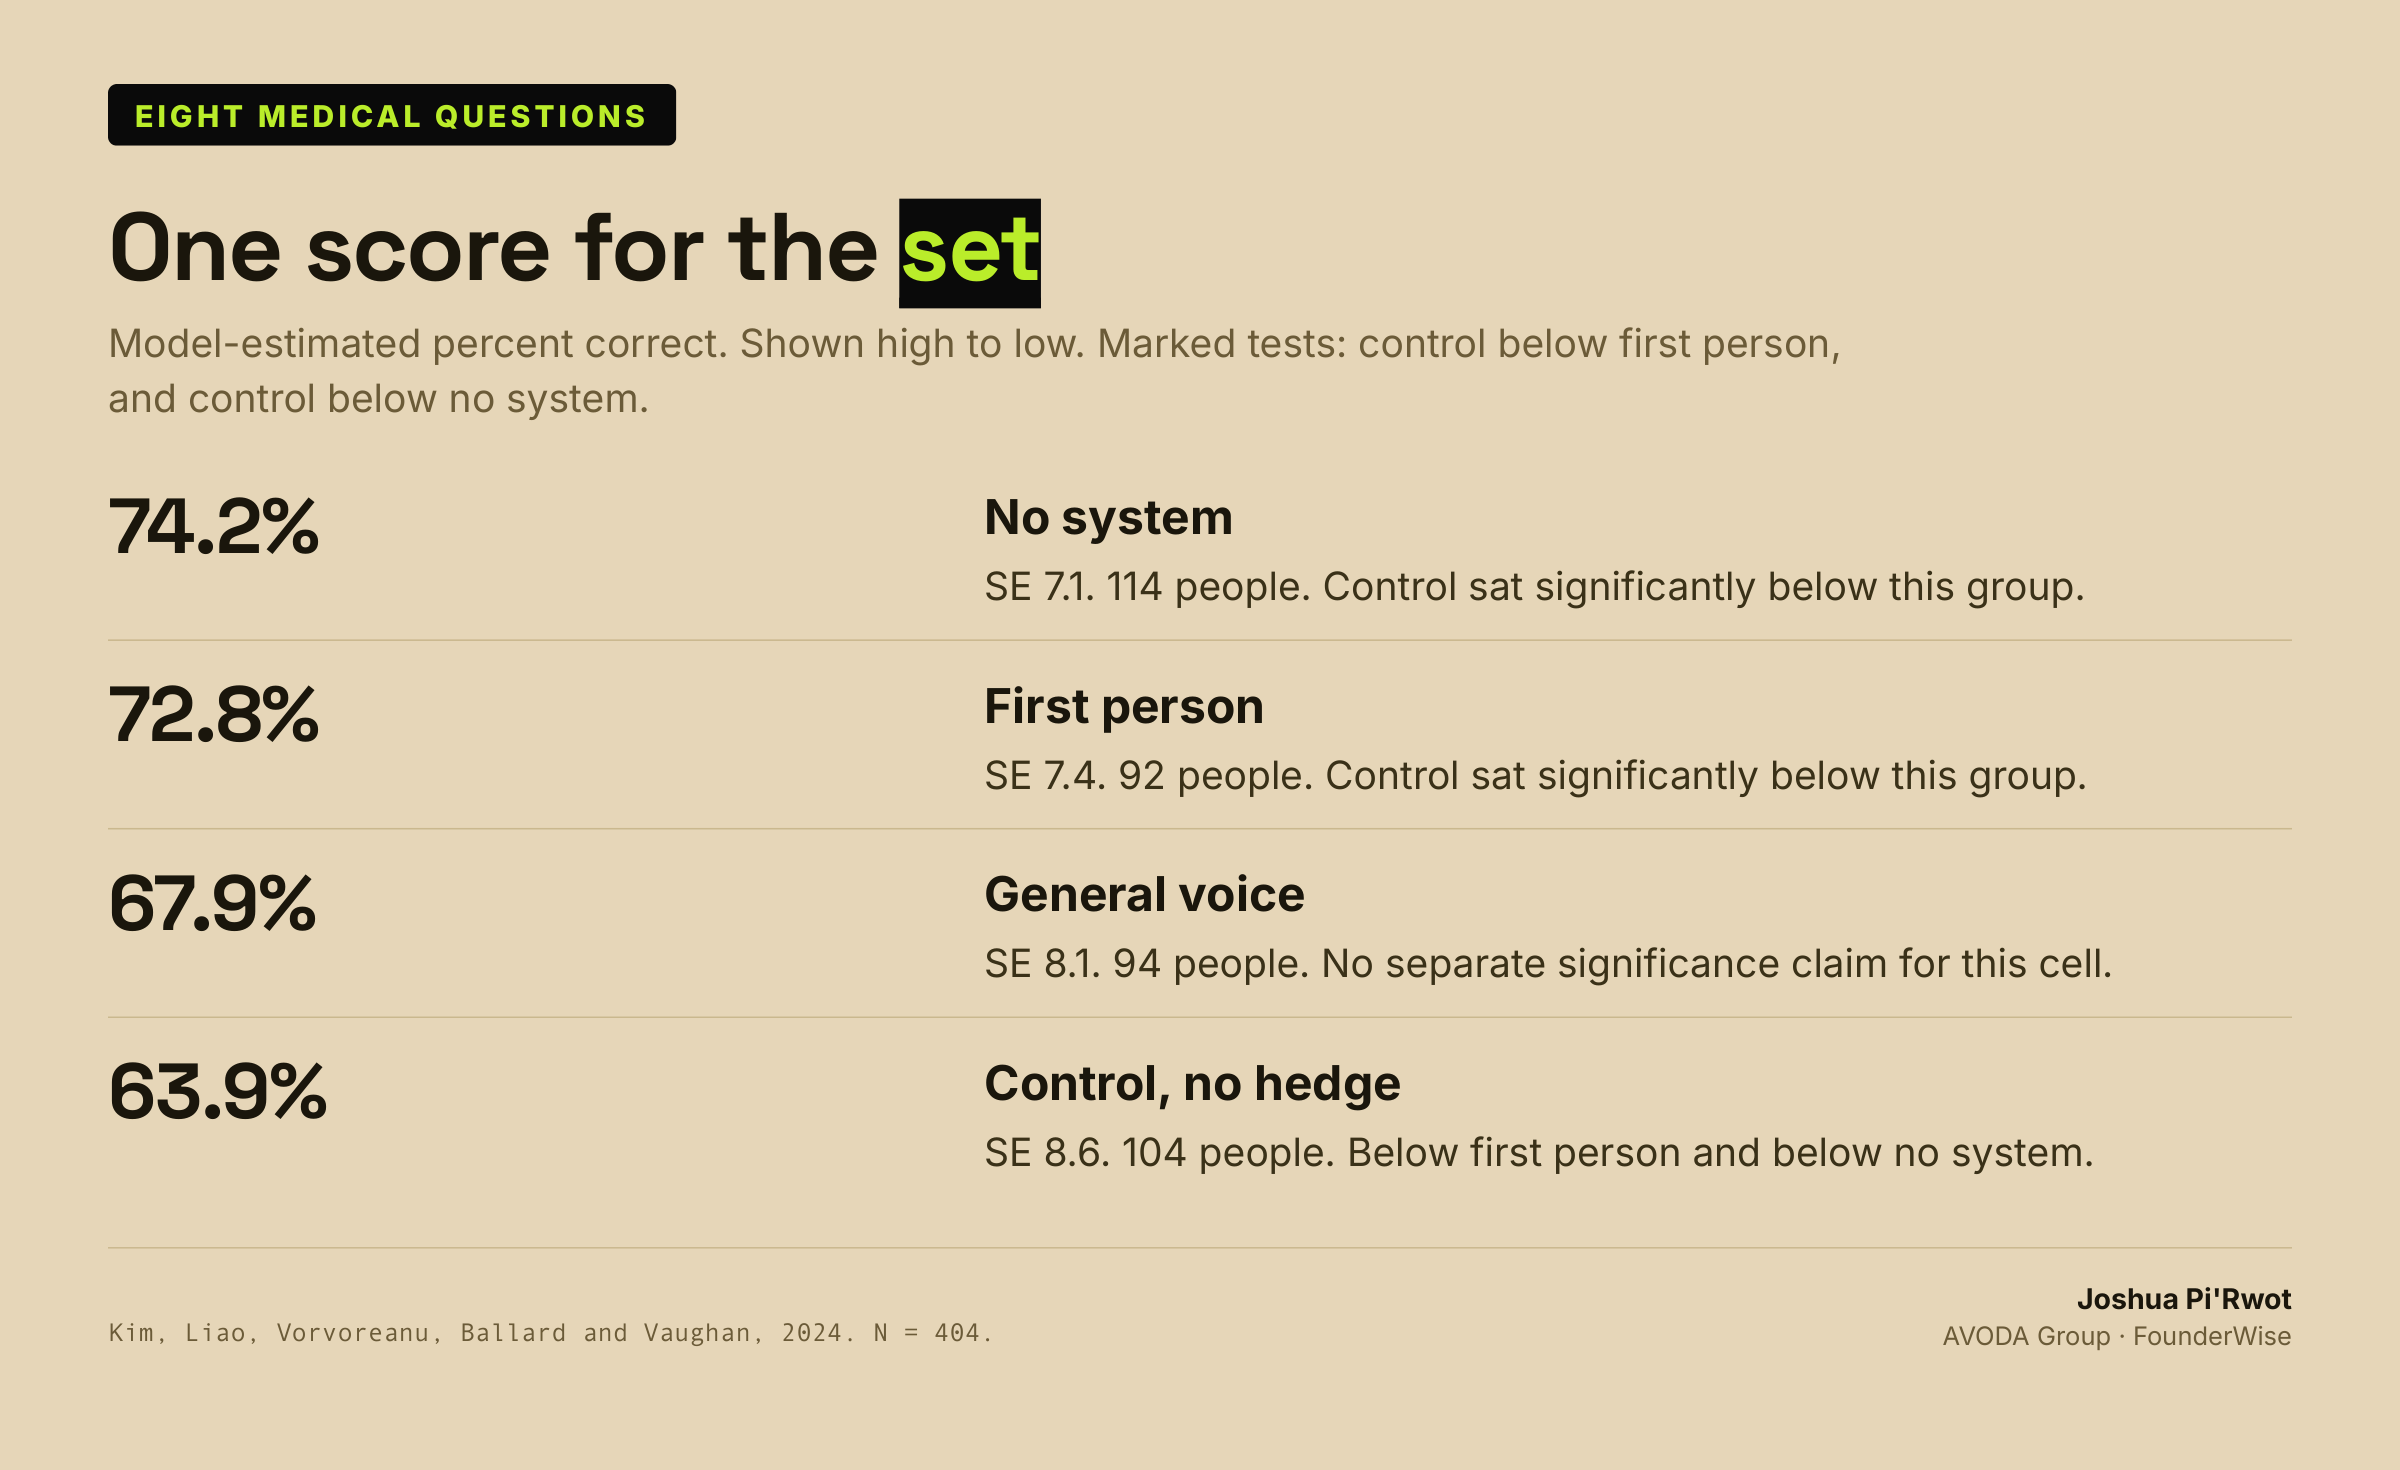
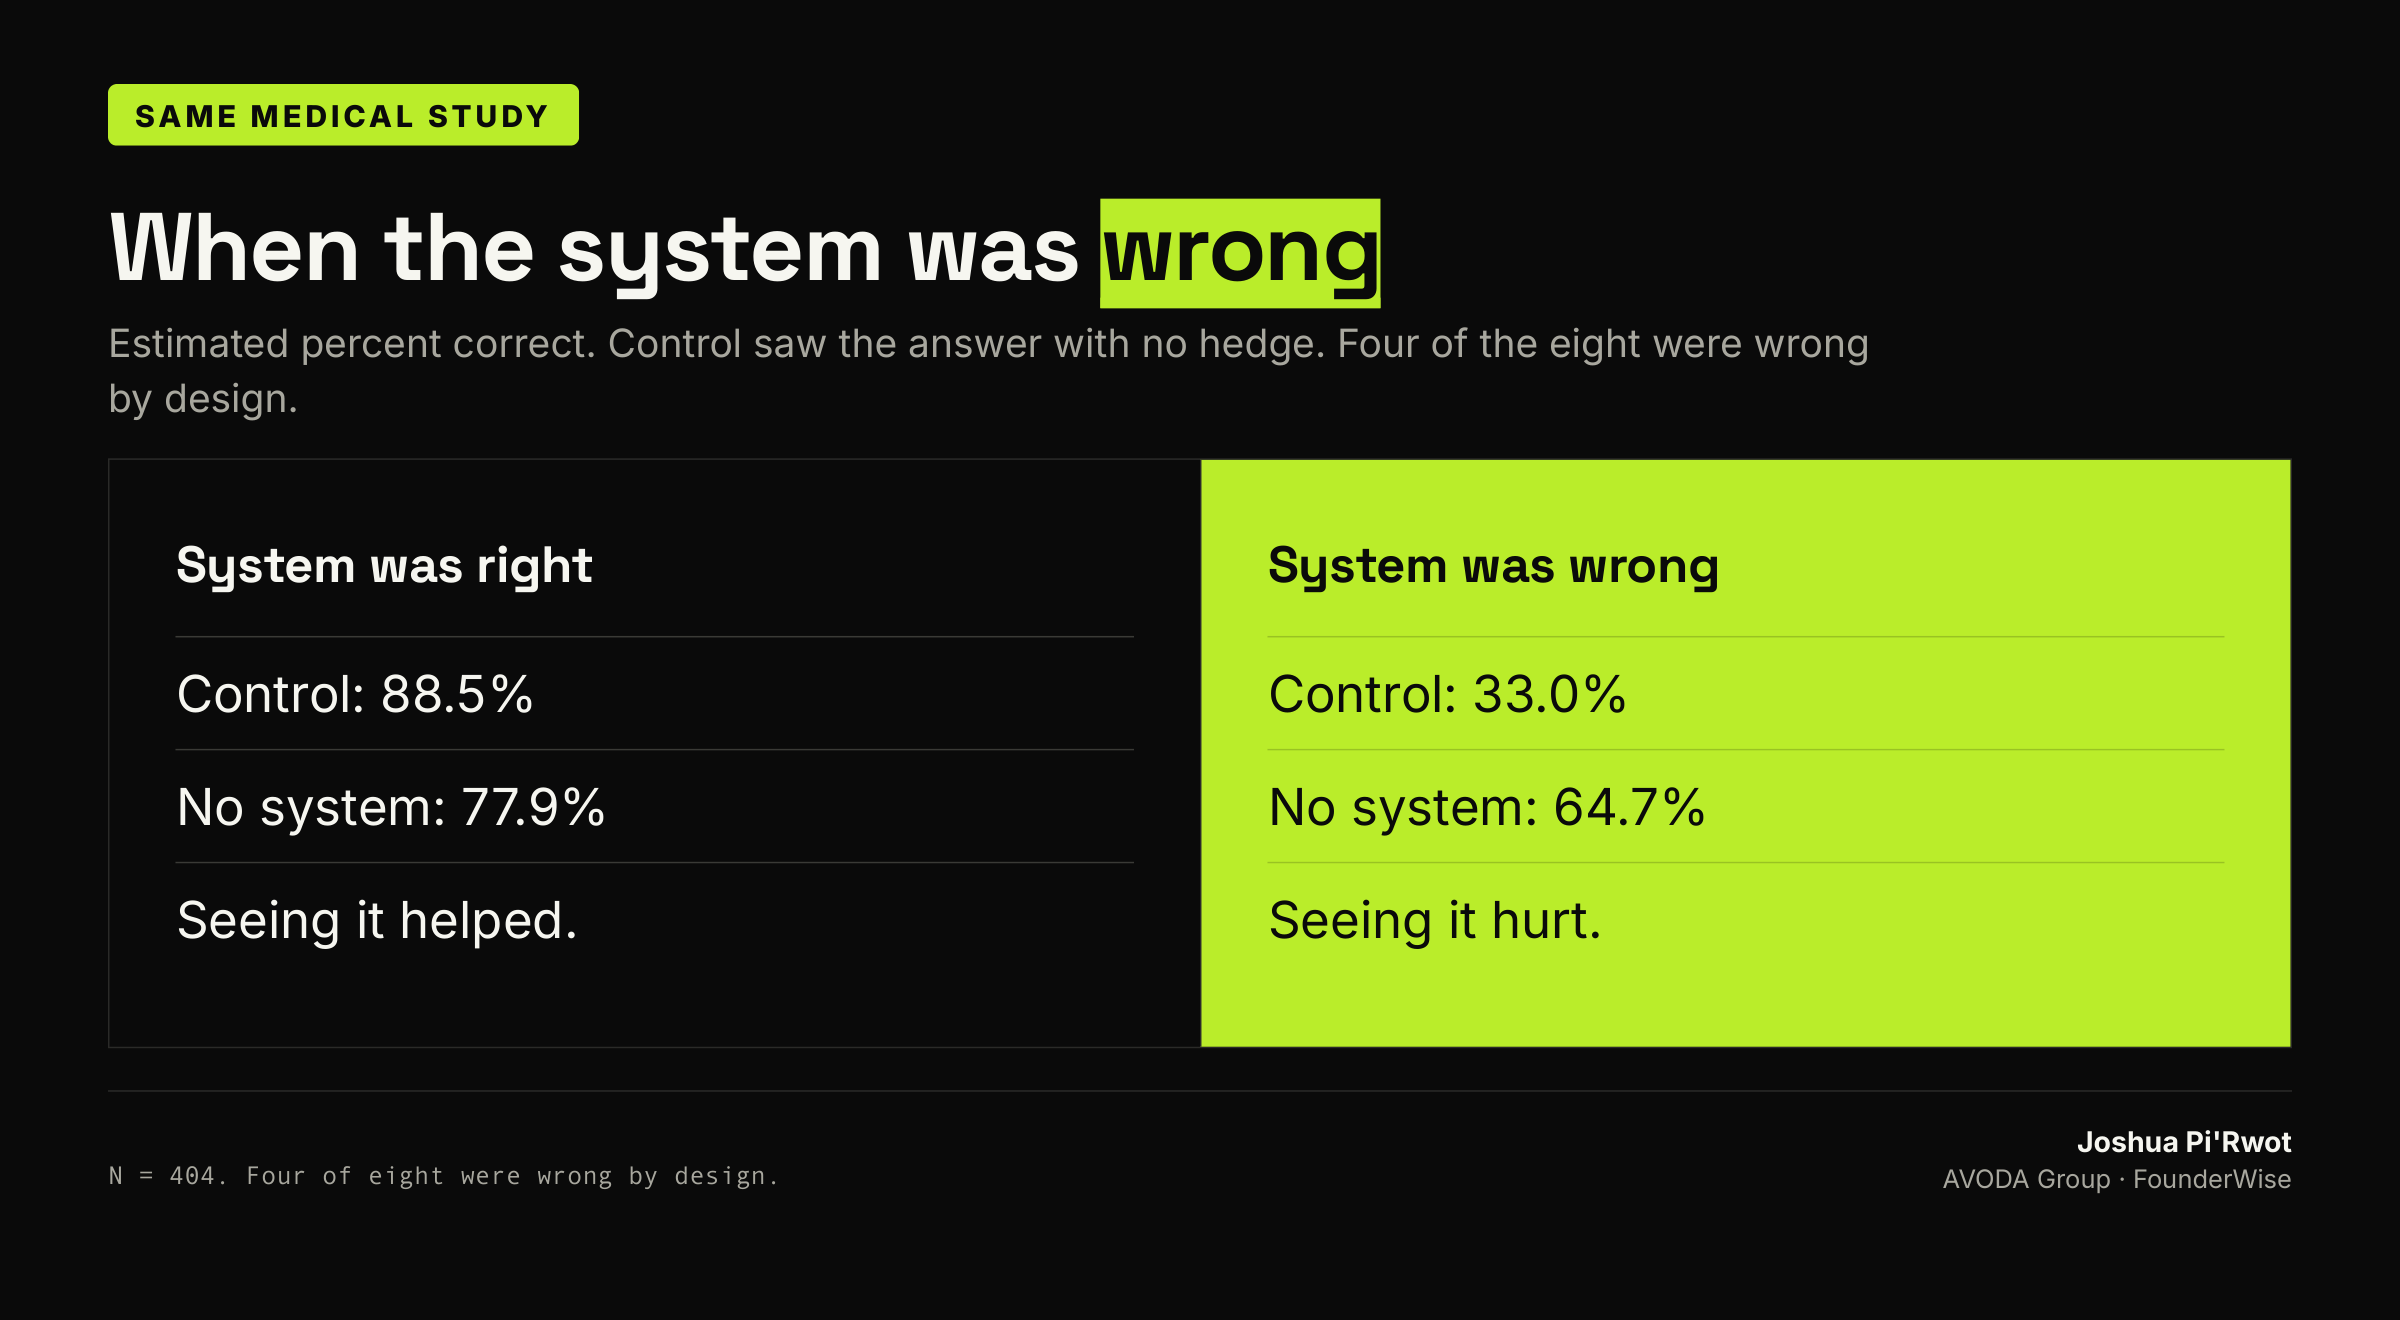
The second study is Sunnie S. Y. Kim, Q. Vera Liao, Mihaela Vorvoreanu, Stephanie Ballard and Jennifer Wortman Vaughan, presented in Rio de Janeiro from 3 to 6 June 2024. The final sample is 404 people, and eight medical questions. The system was right on four and wrong on four, by design. That split is not a measured accuracy rate out in the world.
Overall, people with no system scored 74.2%. People with an unhedged system scored 63.9%. People who saw a first-person hedge scored 72.8%. One of the sentences in the materials is “I’m not sure, but it seems like.” A general-voice hedge landed at 67.9%. The contrasts the authors mark are the unhedged system below the first-person group, and the unhedged system below no system. I am not claiming a separate significance mark for the general voice.
When the system was right, seeing it helped: 88.5%, against 77.9% with no system. When it was wrong, seeing it hurt: 33.0%, against 64.7% with no system. The hedges narrowed the hole on the wrong questions. The authors say both hedge groups still finished those questions behind the people who had no system.
What the two pages will and will not support
Both samples are US crowdworkers. One task is a plate of food, with the high-carb ingredient made obvious. The other is eight medical questions with the errors assigned in advance. The medical sample, the authors say, is younger and more educated than the country. None of that is a ledger, a tax filing, or a supplier quote.
If the firm has fewer than 20 people, the Census story places it in the band whose reported use did not move from December 2025 to May 2026. At four employees or fewer, the band is the one the Bureau put under 20%.
If a model is in use on a question that has a wrong answer, write yours down before you open the output. On the plates the model got wrong, that step scored 0.27. Reading the explanation and going with it scored 0.08. No model scored 0.49.
Sources
- Census Bureau story, Adam Grundy, Cory Breaux and Dhanapati Khatiwoda, 26 May 2026. census.gov/library/stories/2026/05/ai-use-businesses.html
- Buçinca, Malaya and Gajos, April 2021, CSCW. arxiv.org/pdf/2102.09692
- Kim, Liao, Vorvoreanu, Ballard and Wortman Vaughan, FAccT 2024. arxiv.org/html/2405.00623
The story’s data page and working paper were not opened. The paper Kim cites on a first-person sentence amplifying a confident claim was not re-read. No number in this piece comes from those.